Max Woolf on why OpenAI and Anthropic cut LLM prices by up to 80%
Max Woolf's timeline of OpenAI and Anthropic price cuts, and why cache-read prices are the ones that matter for coding agents.
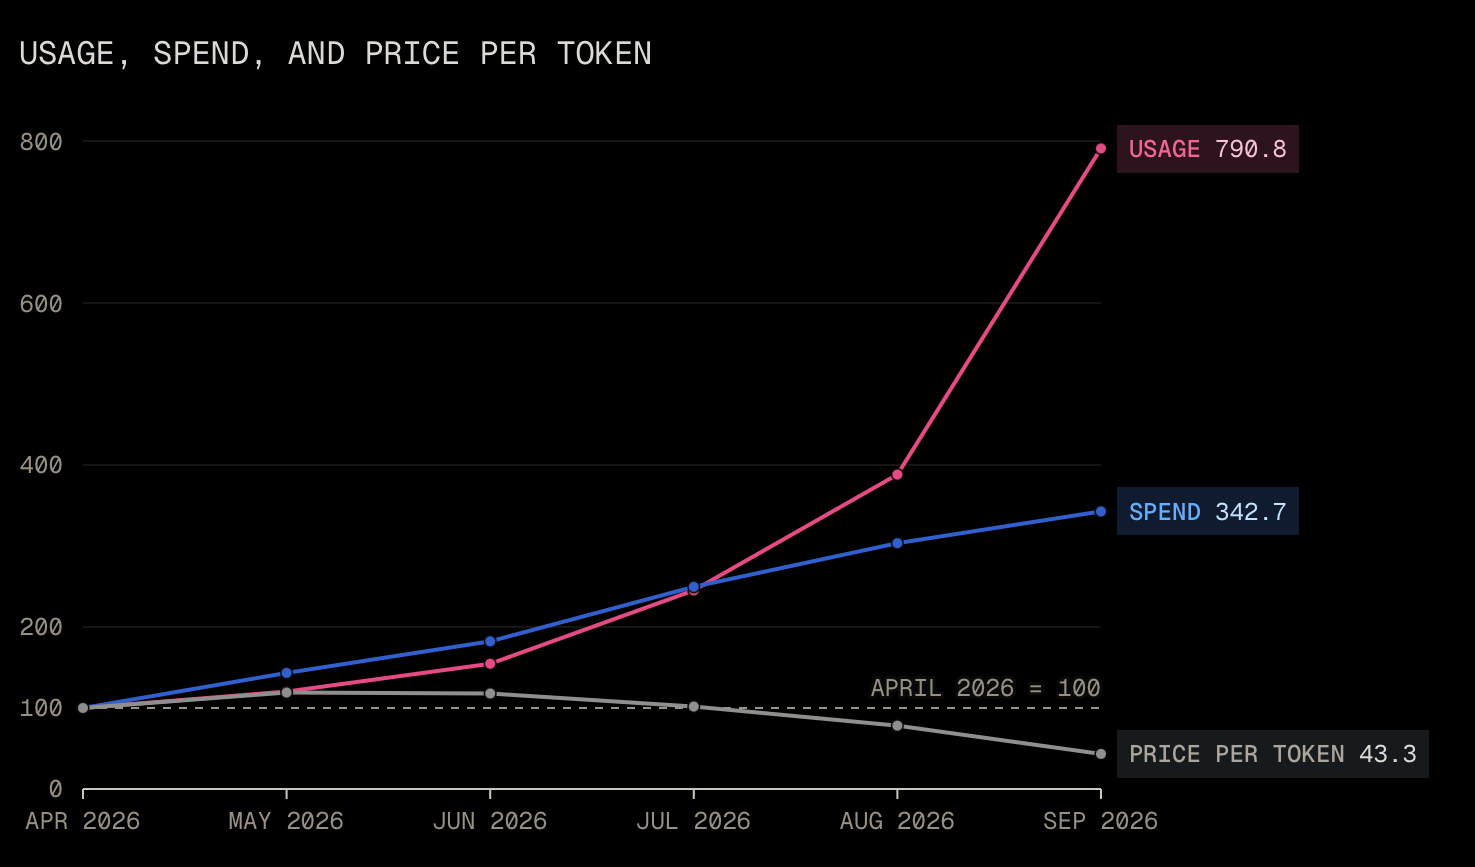
OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why? (Max Woolf, October 25, 2026)
Max Woolf lays out every OpenAI and Anthropic price change since June as a dated timeline, then asks the obvious question: why would two companies heading toward IPOs cut their main revenue line this hard? His answers are competition from open-weight models served by dozens of inference providers, and models that got cheaper to serve.
The paragraph I’d send to anyone who budgets for coding agents:
When using agents for coding, cache read costs are the vast majority (96% - 99%) of the total token expenditure as the cache is what contains the entire previous conversation each turn.
That’s why the cuts that matter for agents are the cache-read ones, and they’re the easy ones to miss in a launch post. I checked the current list prices on the primary pages today. Anthropic’s pricing page has Opus 5.5 at $4 input, $20 output and $0.20 cache read per million tokens, against $5, $25 and $0.50 for the now-legacy Opus 5. Input dropped 20%, cache reads dropped 60%. OpenAI’s API pricing has gpt-6.1-sol at $2 input, $10 output and $0.10 cached input (up to 272K tokens).
His open-weight argument matches what I found when I priced one coding-agent session on Kimi K3.1 Pro: the half-price headline shrank once cache reads were in the bill, because Kimi and Opus 5.5 charge the same $0.20 for them. Woolf counts 29 providers serving DeepSeek V4.1 Flash 1017 on OpenRouter, up from 13 for V4 Flash in May. With that much competition I don’t see token prices going back up.
The part that should worry anyone on a subscription: Woolf reports that when GPT-6.1 Sol launched, OpenAI halved the usage allowance on the $200/month Codex tier. If he’s right, subscription limits can shrink even while per-token prices fall. Watch the limits as closely as the prices.
Today’s article, Context inertia: why long-running agents get stuck, runs the same cache-read math on a long agent run, with and without context resets.
Via Hacker News.